Report2CT: Radiology Report-Conditional 3D CT Generation
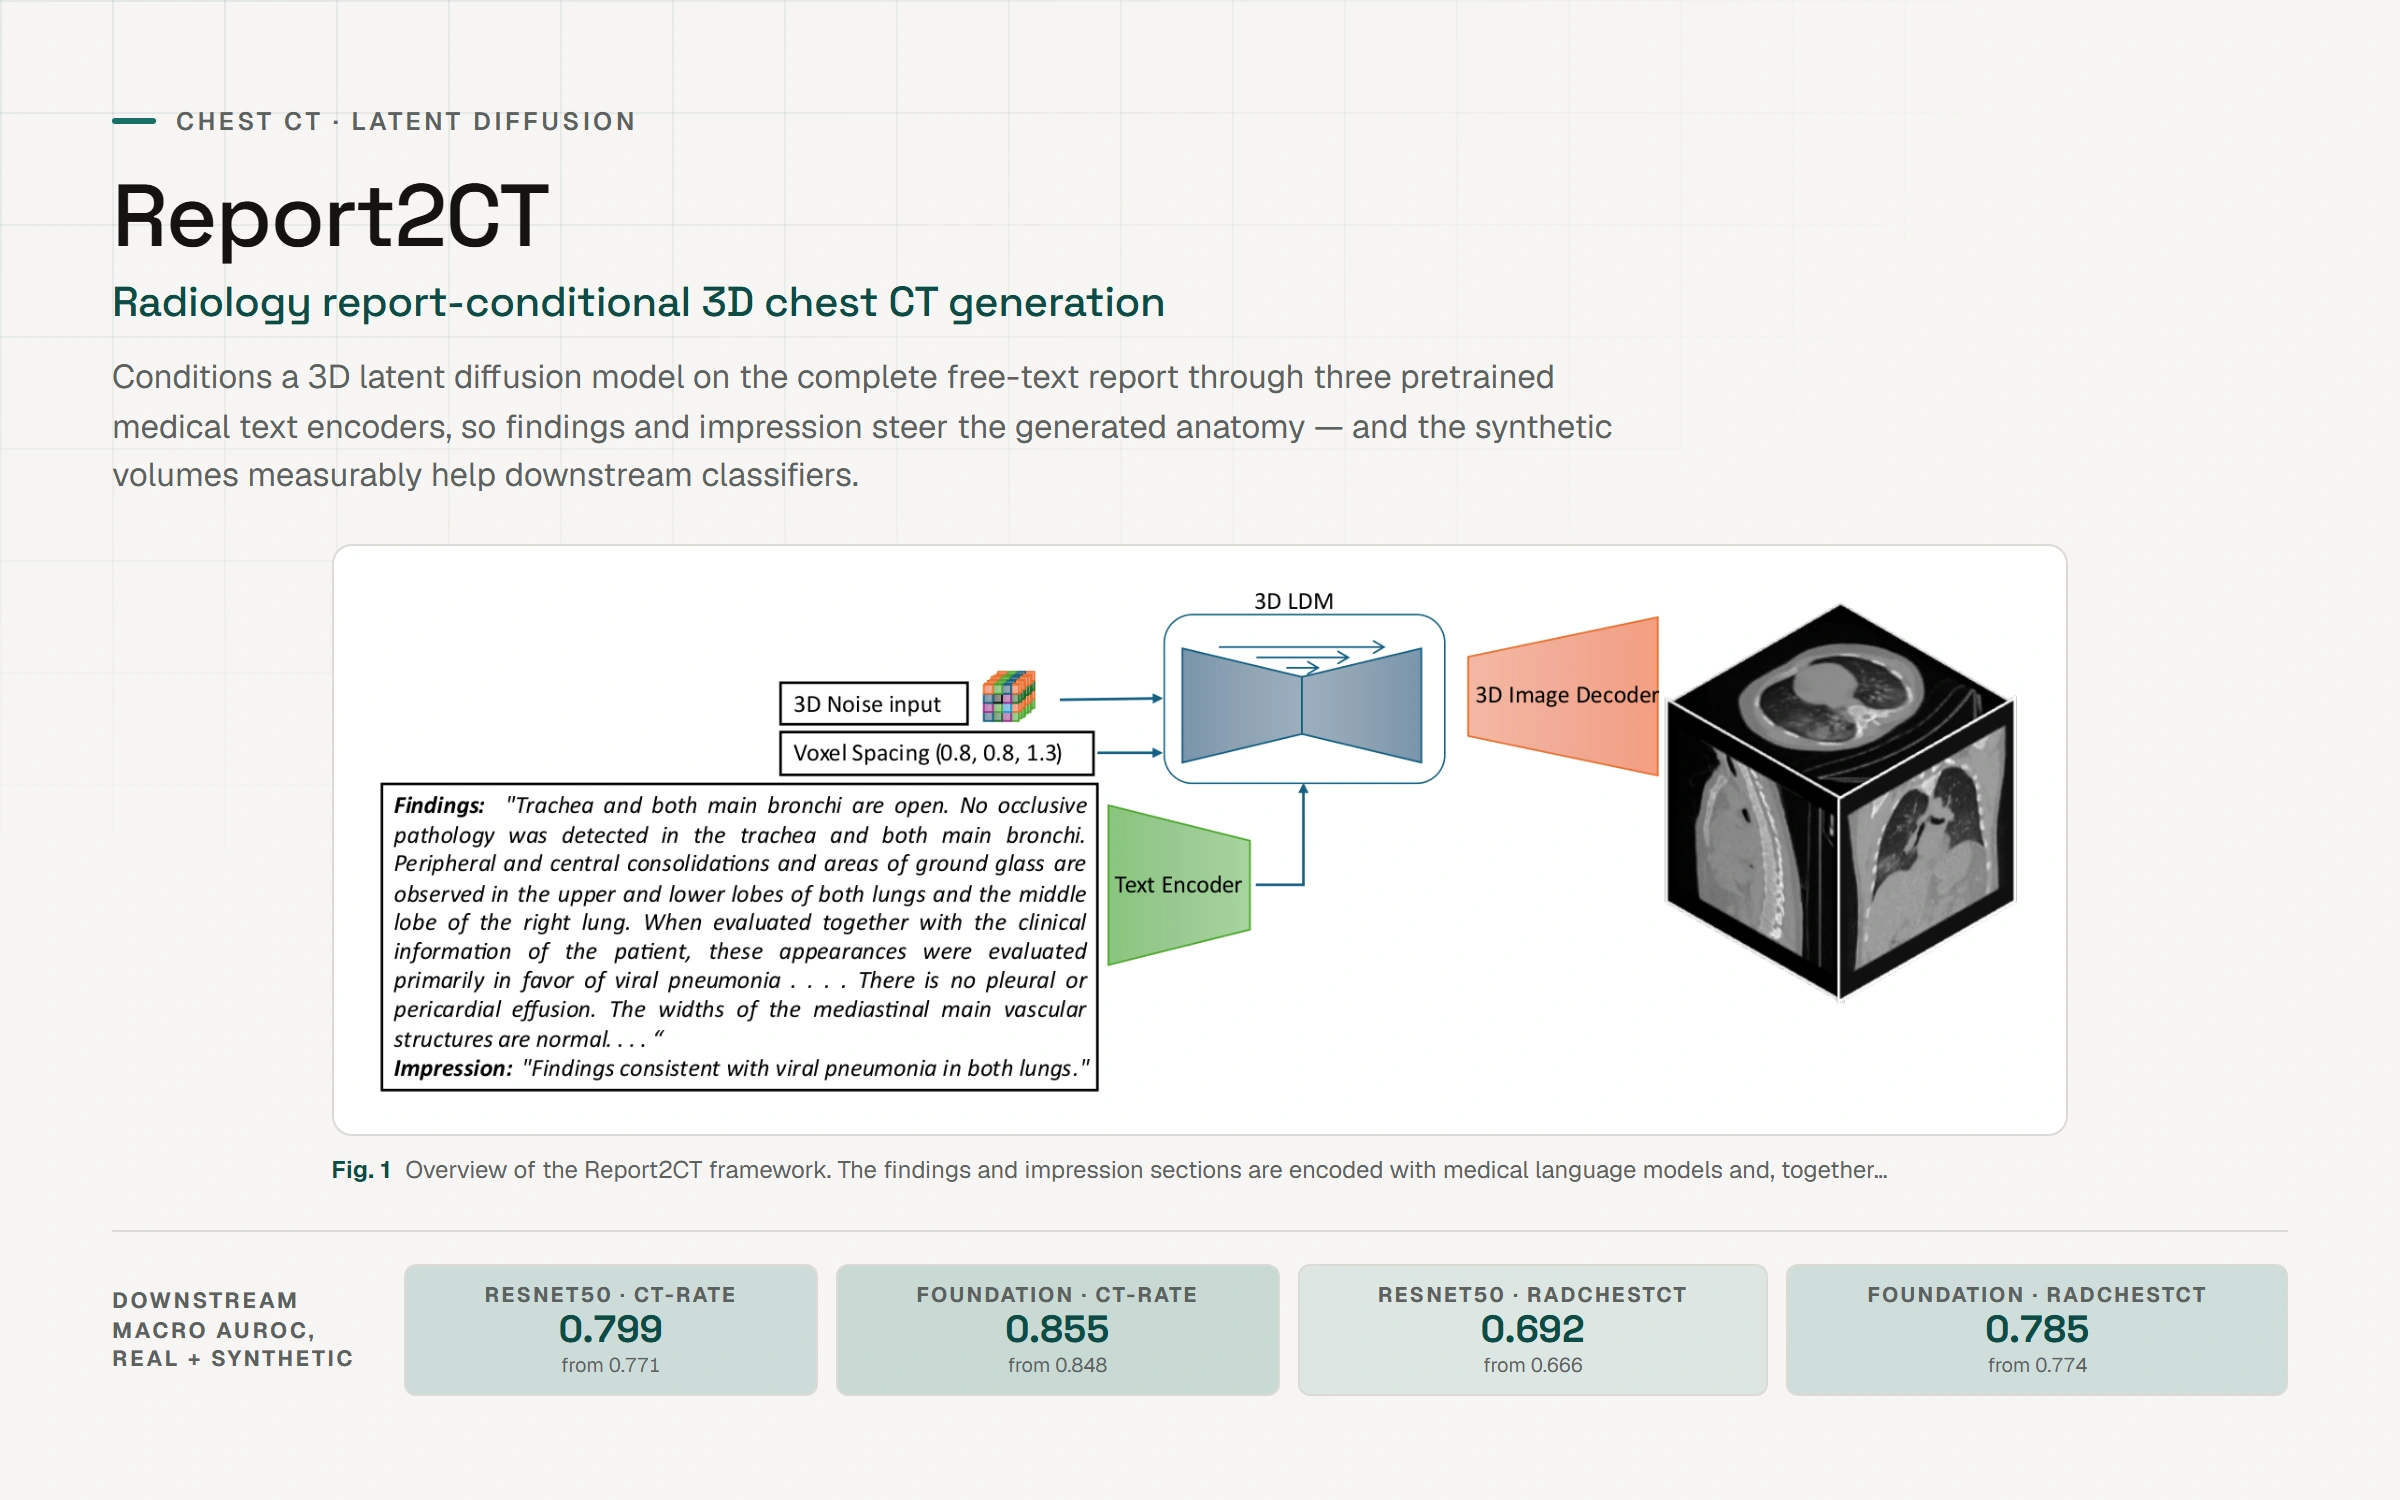
Text-to-image latent diffusion models have advanced medical image synthesis, but 3D CT generation remains limited, and existing approaches rely on simplified prompts that neglect the rich semantic detail in full radiology reports. Report2CT is a radiology report-conditional latent diffusion framework that synthesizes 3D chest CT volumes directly from free-text reports, integrating three pretrained medical text encoders (BiomedVLP CXR BERT, MedEmbed, and ClinicalBERT) to capture nuanced clinical context. The model was trained on 20,000 CT volumes from the CT-RATE dataset, conditioned on complete reports and voxel spacing. Evaluated with Frechet Inception Distance and CLIP-based semantic alignment against the GenerateCT baseline, Report2CT generated anatomically consistent volumes with strong text-image alignment; multi-encoder conditioning improved CLIP scores, and classifier-free guidance further enhanced alignment with only a minor FID trade-off. Report2CT ranked first in the VLM3D Challenge at MICCAI 2025 on Text-Conditional CT Generation, achieving state-of-the-art performance across all evaluation metrics.
Abstract
Text to image latent diffusion models have recently advanced medical image synthesis, but applications to 3D CT generation remain limited. Existing approaches rely on simplified prompts, neglecting the rich semantic detail in full radiology reports, which reduces text image alignment and clinical fidelity. We propose Report2CT, a radiology report conditional latent diffusion framework for synthesizing 3D chest CT volumes directly from free text radiology reports, incorporating both findings and impression sections using multiple text encoders. Report2CT integrates three pretrained medical text encoders (BiomedVLP CXR BERT, MedEmbed, and ClinicalBERT) to capture nuanced clinical context. Radiology reports and voxel spacing information condition a 3D latent diffusion model trained on 20,000 CT volumes from the CT-RATE dataset.
Model performance was evaluated using Frechet Inception Distance (FID) for real-synthetic distributional similarity and CLIP-based metrics for semantic alignment, with additional qualitative and quantitative comparisons against the GenerateCT model. Report2CT generated anatomically consistent CT volumes with excellent visual quality and text-image alignment. Multi-encoder conditioning improved CLIP scores, indicating stronger preservation of fine-grained clinical details in the free-text radiology reports. Classifier-free guidance further enhanced alignment with only a minor trade-off in FID.
We ranked first in the VLM3D Challenge at MICCAI 2025 on Text-Conditional CT Generation and achieved state-of-the-art performance across all evaluation metrics. By leveraging complete radiology reports and multi-encoder text conditioning, Report2CT advances 3D CT synthesis, producing clinically faithful and high-quality synthetic data.